import numpy as np


def tournament_selection(lengths, t, rng):
    """Return the index of the shortest of t tours chosen at random
    with replacement."""
    candidates = rng.integers(len(lengths), size=t)
return min(candidates, key=lambda i: lengths[i])31 Genetic Algorithm
Local search (Chapter 29) and simulated annealing (Chapter 30) keep a single current solution and iterate it to a neighboring solution. Multi-start local search uses many initial solutions, but its local searches are independent. The solution found by each local search is not used by the others. Genetic algorithms were introduced by Holland (1975) and popularized by Goldberg (1989). A genetic algorithm (GA) keeps a set of solutions and creates new solutions by combining those solutions.
The approach that uses a collection of solutions is called population methods and GAs are the most widely known population method. Also, they are the most widely known type of evolutionary algorithm (Eiben and Smith 2015, sec. 6.1), a family of algorithms whose vocabulary comes from biological evolution.
A solution is called an individual or a chromosome, and its quality is called its fitness. The two solutions that are combined are called parents, and the new solution is called an offspring or a child. One iteration of the algorithm is called a generation. GAs are usually described for maximizing the fitness. Since we minimize f, a better solution in this chapter is one with a smaller value of f.
Let P = \{\mathbf{x}_1, \mathbf{x}_2, \ldots, \mathbf{x}_{N}\} be the population, and let N be its size. The population size normally remains constant throughout the algorithm. Algorithm 1 shows the general scheme of a GA.
\begin{algorithm} \caption{General Scheme of a Genetic Algorithm} \begin{algorithmic} \State initialize population $P$ \State evaluate each individual in $P$ \While{stopping criterion not met} \State select parents from $P$ \State crossover the parents to create offspring \State mutate the offspring \State evaluate each offspring \State select the next population $P$ \EndWhile \State \textbf{return} the best solution found \end{algorithmic} \end{algorithm}
After the initial population is generated and evaluated, each generation consists of five steps:
- Parent selection chooses solutions in P as parents.
- Crossover creates offspring that inherit parts of two parents.
- Mutation changes the offspring slightly at random.
- Evaluation computes the value of f for each offspring.
- Survivor selection chooses the solutions for the next population from the current population and the offspring.
Crossover and mutation are konown as variation operators, because they create new solutions from existing ones.
Like local search, the GA is a framework rather than a complete algorithm, and its many variants differ in how these steps are carried out. To implement a GA, we need to decide
- representation of the solutions,
- Selection of parents,
- Variation operators (crossover and mutation),
- Evaluation of the offspring, and
- Selection of the next population.
The representation comes first, because crossover and mutation operate on it. It plays a role similar to that of the neighborhood in local search.
In this chapter, we return to the TSP of Chapter 29. A tour is represented by a permutation \mathbf{x} = (x_1, \ldots, x_n) of the n cities, where x_k is the kth city visited. Every permutation is a feasible tour, so as long as crossover and mutation produce permutations, the GA never creates an infeasible solution. This way of handling constraints is called solution encoding.
The following sections describe the parent selection, crossover, and mutation for permutations. Then, we implement a GA for the TSP.
31.1 Parent Selection
Parent selection chooses the parents. Better solutions should be chosen more often, so that their good parts are passed on to the offspring. However, if mostly the best solutions are chosen, the population soon consists of copies of a few solutions, and the search finds few new solutions. In the GA, the higher the selection pressure, the more strongly selection prefers better solutions. Finding a good balance between selection pressure is important and this is also known as the exploration-exploitation trade-off.
In the following, we describe two widely used selection methods: tournament selection and fitness-proportional selection.
31.1.1 Tournament Selection
Tournament selection chooses t solutions in P at random with replacement and returns the best of them. The parameter t \geq 1 is called the tournament size. With t = 1, every solution in P is chosen with the same probability, and a larger t gives a higher selection pressure. It has become the most widely used selection method in GAs (Luke 2013, sec. 3.2.3). Algorithm 2 shows the procedure.
\begin{algorithm} \caption{Tournament Selection} \begin{algorithmic} \Require population $P$, tournament size $t \geq 1$ \Ensure selected solution \For{$j = 1, \ldots, t$} \State $\mathbf{z}_j \gets$ a solution chosen from $P$ uniformly at random \EndFor \State \textbf{return} a solution among $\mathbf{z}_1, \ldots, \mathbf{z}_t$ with the smallest value of $f$ \end{algorithmic} \end{algorithm}
The function tournament_selection() implements Algorithm 2. Its argument lengths lists the tour lengths in the population. The function returns the index of the selected tour.
Figure 31.1 shows how the tournament size controls the selection pressure. It considers a population of 20 solutions \mathbf{x}_1, \ldots, \mathbf{x}_{20} with f(\mathbf{x}_1) < f(\mathbf{x}_2) < \cdots < f(\mathbf{x}_{20}), so that \mathbf{x}_r is the rth best solution, and shows the fraction of 100,000 tournaments won by each \mathbf{x}_r. With t = 1, every solution wins about 5% of the tournaments, as with random selection. As t increases, better solutions win more often: with t = 5, \mathbf{x}_1 wins about 23% of the tournaments, and \mathbf{x}_{15}, \ldots, \mathbf{x}_{20} almost never win. Exercise 31.2 derives these probabilities.
Code
import matplotlib.pyplot as plt

rng = np.random.default_rng(0)
n_solutions, n_tournaments = 20, 100_000
values = list(range(n_solutions))  # f(x_r) = r - 1
ranks = np.arange(1, n_solutions + 1)

fig, ax = plt.subplots(figsize=(6, 3.5))
for t, marker in zip([1, 2, 3, 5], ["o", "s", "^", "D"]):
    selected = [tournament_selection(values, t, rng) for _ in range(n_tournaments)]
    frequency = np.bincount(selected, minlength=n_solutions) / n_tournaments
    ax.plot(
        ranks,
        frequency,
        color="black",
        linewidth=1,
        marker=marker,
        markersize=4,
        markerfacecolor="white",
        label=f"$t = {t}$",
    )
ax.set(
    xlabel=r"Rank $r$ of the solution $\mathbf{x}_r$ (1 = best)",
    ylabel="Fraction of tournaments won",
    xticks=[1, 5, 10, 15, 20],
    xlim=(0.5, 20.5),
    ylim=(0, None),
)
ax.legend(frameon=False)
ax.spines[["top", "right"]].set_visible(False)
fig.tight_layout()
plt.show()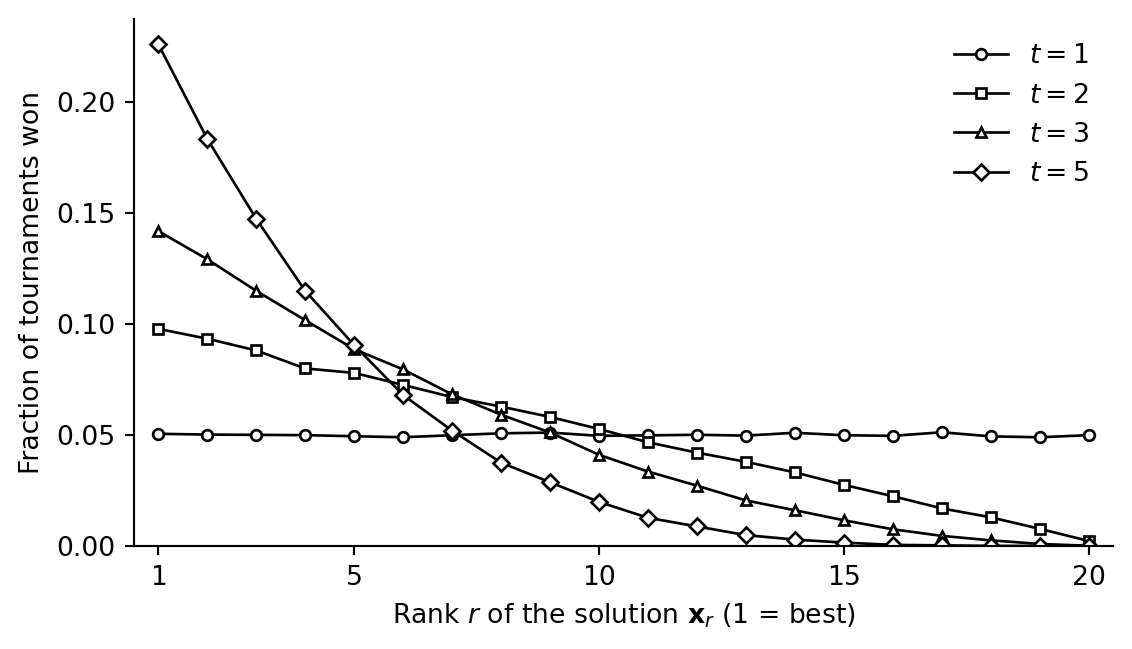
31.1.2 Fitness-Proportional Selection
In fitness-proportional selection, also called roulette-wheel selection, each solution \mathbf{x}_i in P has a fitness F_i \geq 0, where a larger value is better, and is chosen with probability
p_i = \frac{F_i}{\sum_{j=1}^{N} F_j}, \quad i = 1, \ldots, N.
The name comes from a roulette wheel on which each solution \mathbf{x}_i has a sector of size F_i (Figure 31.2). Spinning the wheel once selects one solution, and \mathbf{x}_i is selected with probability p_i.
Code
F = np.array([4, 3, 2, 1])
r = 5.5
bounds = np.concatenate([[0], np.cumsum(F)])  # 0, F_1, F_1 + F_2, ...
selected = np.searchsorted(bounds, r, side="right") - 1  # bounds[i] <= r < bounds[i + 1]


def angle(t):
    """Return the polar angle of the point at position t on the circumference,
    where positions run clockwise from the top."""
    return np.pi / 2 - 2 * np.pi * t / F.sum()


fig, ax = plt.subplots(figsize=(4, 4))
ax.pie(
    F,
    startangle=90,
    counterclock=False,
    colors=["lightgray" if i == selected else "white" for i in range(len(F))],
    wedgeprops=dict(edgecolor="black", linewidth=1),
)
for i in range(len(F)):
    a = angle((bounds[i] + bounds[i + 1]) / 2)
    ax.text(
        0.68 * np.cos(a),
        0.68 * np.sin(a),
        f"$\\mathbf{{x}}_{i + 1}$\n$F_{i + 1} = {F[i]}$",
        ha="center",
        va="center",
    )
for b in bounds[:-1]:
    a = angle(b)
    ax.text(1.13 * np.cos(a), 1.13 * np.sin(a), f"{b}", ha="center", va="center")
a = angle(r)
ax.annotate(
    f"$r = {r}$",
    xy=(np.cos(a), np.sin(a)),
    xytext=(1.5 * np.cos(a), 1.5 * np.sin(a)),
    ha="center",
    va="center",
    arrowprops=dict(arrowstyle="-|>", color="black", mutation_scale=14),
)
ax.set(xlim=(-1.25, 1.25), ylim=(-1.65, 1.25), aspect="equal")
fig.tight_layout()
plt.show()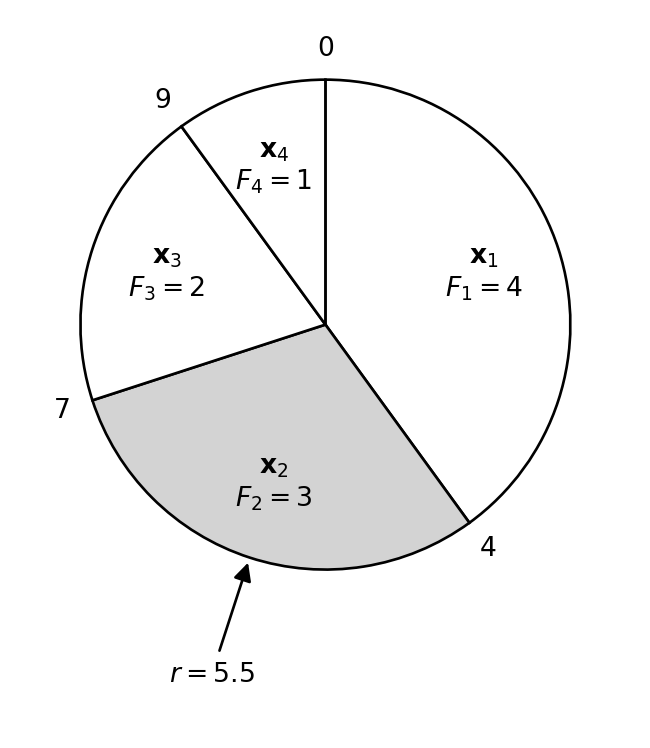
Algorithm 3 shows the procedure. It chooses a point r \in [0, \sum_{j=1}^{N} F_j) on the wheel at random and returns the solution whose sector contains r, that is, the \mathbf{x}_i with \sum_{j=1}^{i-1} F_j \leq r < \sum_{j=1}^{i} F_j.
\begin{algorithm} \caption{Roulette-Wheel Selection} \begin{algorithmic} \Require population $P = (\mathbf{x}_1, \ldots, \mathbf{x}_{N})$, fitness $F_1, \ldots, F_{N} \geq 0$ with $\sum_{j=1}^{N} F_j > 0$ \Ensure selected solution \State $r \gets$ a number chosen from $[0, \sum_{j=1}^{N} F_j)$ uniformly at random \State \textbf{return} the solution $\mathbf{x}_i$ with $\sum_{j=1}^{i-1} F_j \leq r < \sum_{j=1}^{i} F_j$ \end{algorithmic} \end{algorithm}
For minimization problems, the fitness must be derived from f. A common choice is F_i = f_{\max} - f(\mathbf{x}_i), where f_{\max} is the largest value of f in the population. With this choice, the worst solution has zero fitness and is never chosen. Moreover, the probabilities depend on the differences between the values of f, so a single very bad solution can make the selection almost uniform among the others (Exercise 31.3).
31.1.3 Ranking selection
Ranking selection avoids this problem by assigning the probabilities according to the ranks of the solutions in the population rather than their values of f (Eiben and Smith 2015, sec. 5.2.2). In tournament selection, too, the probability of choosing a solution depends only on its rank (Exercise 31.2).
31.2 Crossover for Permutations
Crossover creates an offspring \mathbf{y} from two parents \mathbf{u} = (u_1, \ldots, u_n) and \mathbf{v} = (v_1, \ldots, v_n).
31.2.1 Order Crossover
Order crossover (OX) always generates a legitimate permutation. It keeps a segment of \mathbf{u} and takes the relative order of the other cities from \mathbf{v}.
- Choose two cut points a < b in \{0, 1, \ldots, n\}. Copy the segment (u_{a+1}, \ldots, u_b) of \mathbf{u} to positions a + 1, \ldots, b of \mathbf{y}.
- Read \mathbf{v} from position b + 1 to position n and then from position 1 to position b, skipping the cities that are already in \mathbf{y}. Write the cities in this order to positions b + 1, \ldots, n and then to positions 1, \ldots, a of \mathbf{y}.
A second offspring can be created by exchanging the roles of \mathbf{u} and \mathbf{v}.
Example 31.1 (Order crossover) Consider the parents \mathbf{u} = (1, 2, 3, 4, 5, 6, 7, 8, 9) and \mathbf{v} = (9, 3, 7, 8, 2, 6, 5, 1, 4) with the cut points a = 3 and b = 7. This is the example from Eiben and Smith (2015, fig. 4.15 and 4.16). Step 1 copies the segment (4, 5, 6, 7) of \mathbf{u}:
\mathbf{y} = (\cdot, \cdot, \cdot, 4, 5, 6, 7, \cdot, \cdot).
Step 2 reads \mathbf{v} from position 8, which gives 1, 4, 9, 3, 7, 8, 2, 6, 5. Skipping 4, 5, 6, and 7 leaves 1, 9, 3, 8, 2, and these cities are written to positions 8, 9, 1, 2, and 3:
\mathbf{y} = (3, 8, 2, 4, 5, 6, 7, 1, 9).
Figure 31.3 shows the two steps.
Code
import matplotlib.patches as mpatches

u = [1, 2, 3, 4, 5, 6, 7, 8, 9]
v = [9, 3, 7, 8, 2, 6, 5, 1, 4]
a, b = 3, 7
n = len(u)
segment = u[a:b]
# Zero-based positions of v that are read, skipping the cities in the segment,
# and positions of y that are written, both starting at position b + 1
read = [j for j in list(range(b, n)) + list(range(b)) if v[j] not in segment]
write = list(range(b, n)) + list(range(a))
y = [None] * n
y[a:b] = segment
for j_v, j_y in zip(read, write):
    y[j_y] = v[j_v]

gap = 0.3  # horizontal gap at each cut point


def left(j):
    """Return the x-coordinate of the left side of the box at position j."""
    return j + gap * (j >= a) + gap * (j >= b)


fig, ax = plt.subplots(figsize=(6.5, 3.6))


def draw_row(label, row, fills, bottom):
    """Draw a row of boxes with the given cities and fill colors."""
    ax.text(-0.3, bottom + 0.5, label, ha="right", va="center", fontsize=12)
    for j, (city, fill) in enumerate(zip(row, fills)):
        x = left(j)
        ax.add_patch(
            mpatches.Rectangle(
                (x, bottom), 1, 1, facecolor=fill, edgecolor="black", linewidth=1
            )
        )
        ax.text(x + 0.5, bottom + 0.5, str(city), ha="center", va="center", fontsize=12)


def draw_order(positions, bottom):
    """Draw the circled numbers 1, 2, ... below the boxes at the given positions."""
    for t, j in enumerate(positions, start=1):
        center = (left(j) + 0.5, bottom - 0.37)
        ax.add_patch(
            mpatches.Circle(
                center, 0.25, facecolor="white", edgecolor="black", linewidth=0.8
            )
        )
        ax.text(*center, str(t), ha="center", va="center", fontsize=9)


draw_row(r"$\mathbf{u}$", u, ["white"] * n, 3.9)
draw_row(r"$\mathbf{v}$", v, ["lightgray"] * n, 2.65)
for j in range(n):
    if v[j] in segment:  # skipped in step 2
        ax.plot(
            [left(j) + 0.15, left(j) + 0.85], [2.8, 3.5], color="black", linewidth=1
        )
draw_order(read, 2.65)
draw_row(
    r"$\mathbf{y}$", y, ["white" if a <= j < b else "lightgray" for j in range(n)], 0.6
)
draw_order(write, 0.6)
for name, cut in [("a", a), ("b", b)]:
    x = left(cut) - gap / 2
    ax.plot([x, x], [0.1, 5.1], color="black", linestyle="--", linewidth=1)
    ax.text(x, 5.2, f"${name} = {cut}$", ha="center", va="bottom", fontsize=11)
ax.set(xlim=(-0.9, left(n - 1) + 1.1), ylim=(-0.15, 5.7), aspect="equal")
ax.axis("off")
fig.tight_layout()
plt.show()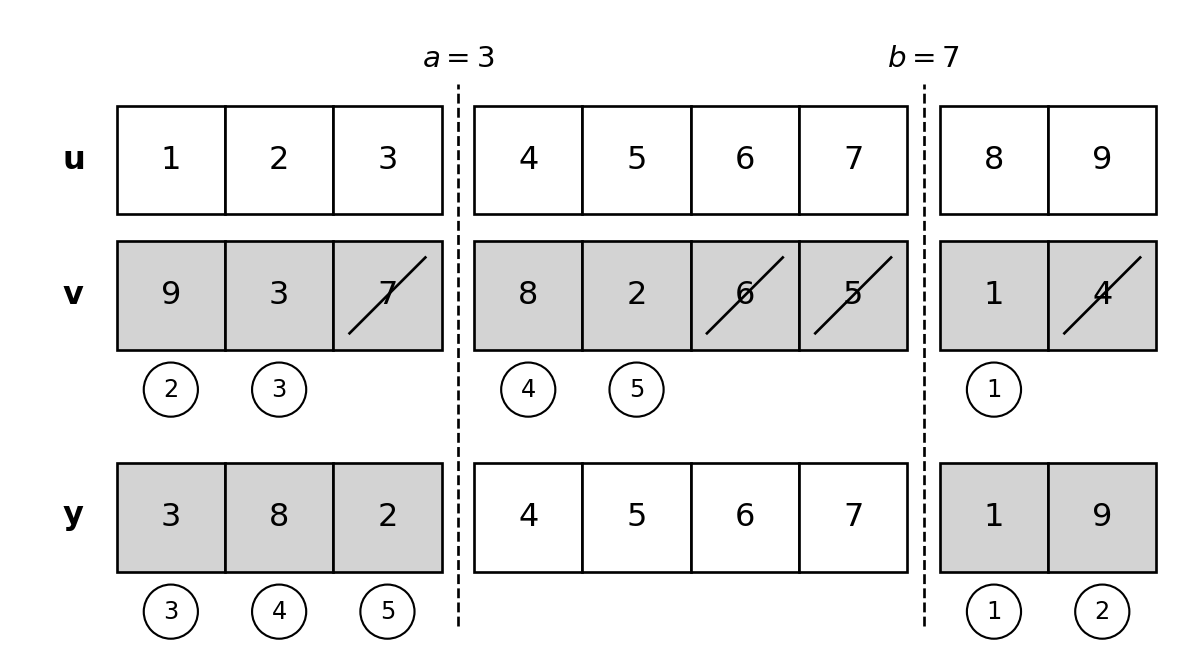
The function order_crossover() implements OX. Python uses zero-based indexing, so the slice u[a:b] is the segment (u_{a+1}, \ldots, u_b), and v[b:] + v[:b] reads \mathbf{v} from position b + 1. Of the cities in rest, the first n - b fill the positions after the segment, and the others fill the positions before it. The following code reproduces Example 31.1.
def order_crossover(u, v, a, b):
    """Order crossover (OX) with cut points a < b."""
    segment = u[a:b]
    # Cities not in the segment, in the order of v read from position b + 1
    rest = [city for city in v[b:] + v[:b] if city not in segment]
    n_after = len(u) - b  # number of positions after the segment
    return rest[n_after:] + segment + rest[:n_after]


u = [1, 2, 3, 4, 5, 6, 7, 8, 9]
v = [9, 3, 7, 8, 2, 6, 5, 1, 4]
print(order_crossover(u, v, 3, 7))
[3, 8, 2, 4, 5, 6, 7, 1, 9]31.2.2 Other Crossover Operators for Permutations
- Partially Mapped Crossover (PMX)
- Edge crossover
31.3 Mutation for Permutations
Mutation operates on a single solution. It creates solutions that selection and crossover alone may not create, and it helps to keep the population diverse. Two common mutations for permutations are the following:
- Swap mutation exchanges the cities at two positions chosen at random.
- Inversion mutation reverses the order of the cities between two positions chosen at random.
Inversion mutation removes two edges and adds two new ones, so it is exactly a 2-opt exchange.
Example 31.2 (Swap and inversion mutations) Consider the tour \mathbf{x} = (1, 2, 3, 4, 5, 6). Swapping the cities at positions 2 and 5 gives (1, 5, 3, 4, 2, 6). This removes the four edges \{1, 2\}, \{2, 3\}, \{4, 5\}, and \{5, 6\} and adds \{1, 5\}, \{3, 5\}, \{2, 4\}, and \{2, 6\}.
Reversing the cities at positions 2 to 5 gives (1, 5, 4, 3, 2, 6). This removes only \{1, 2\} and \{5, 6\} and adds \{1, 5\} and \{2, 6\}. It is the 2-opt exchange.
The inversion mutation below uses the functions two_opt_moves() and two_opt_move() from Chapter 29. The following code reproduces their definitions, along with those of delta(), tour_length(), first_improvement(), and local_search(), which we use later.
Code
def two_opt_move(tour, i, j):
    """Remove edges {tour[i], tour[i+1]} and {tour[j], tour[(j+1) % len(tour)]},
    and reconnect the tour by reversing tour[i+1], ..., tour[j]."""
    return tour[: i + 1] + tour[i + 1 : j + 1][::-1] + tour[j + 1 :]


def delta(tour, i, j, D):
    """Change in the tour length caused by two_opt_move(tour, i, j)."""
    n = len(tour)
    a, b = tour[i], tour[i + 1]
    c, d = tour[j], tour[(j + 1) % n]
    return D[a, c] + D[b, d] - D[a, b] - D[c, d]


def two_opt_moves(n):
    """All 2-opt moves (i, j) for a tour of n cities."""
    for i in range(n - 2):
        for j in range(i + 2, n):
            if i == 0 and j == n - 1:
                continue  # {tour[0], tour[1]} and {tour[n-1], tour[0]} are adjacent
            yield i, j


def tour_length(tour, D):
    """Length of the tour, including the edge back to the first city."""
    return sum(D[tour[k - 1], tour[k]] for k in range(len(tour)))


def first_improvement(tour, D):
    """Return the first improving move, or None if there is none."""
    for i, j in two_opt_moves(len(tour)):
        if delta(tour, i, j, D) < 0:
            return i, j
    return None


def local_search(tour, D, select):
    """2-opt local search. Return the local optimum and the tour lengths."""
    lengths = [tour_length(tour, D)]
    move = select(tour, D)
    while move is not None:  # while I(x) is not empty
        i, j = move
        tour = two_opt_move(tour, i, j)
        lengths.append(tour_length(tour, D))
        move = select(tour, D)
    return tour, lengths
The following functions implement the two mutations. The function inversion_mutation() chooses a 2-opt exchange at random, as simulated annealing does in Section 30.2. With the zero-based indices of Python, the inversion in Example 31.2 is two_opt_move(x, 0, 4).
def swap_mutation(tour, rng):
    """Exchange the cities at two positions chosen at random."""
    i, j = rng.choice(len(tour), size=2, replace=False)
    y = tour.copy()
    y[i], y[j] = y[j], y[i]
    return y


def inversion_mutation(tour, rng):
    """Apply a 2-opt exchange chosen at random."""
    moves = list(two_opt_moves(len(tour)))
    i, j = moves[rng.integers(len(moves))]
    return two_opt_move(tour, i, j)


print(two_opt_move([1, 2, 3, 4, 5, 6], 0, 4))
[1, 5, 4, 3, 2, 6]31.4 Survivor Selection
After the offspring are generated, survivor selection chooses the solutions for the next population. Since it determines how the population changes from one generation to the next, this section describes it as part of two complete algorithms: the simple GA, in which the offspring replace the whole population, and the GA with elitism, which keeps the best solutions in the population.
31.4.1 Simple Genetic Algorithm
The simple GA uses the age-based replacement method, in which the offspring replace the whole population: N offspring are created in each generation, and they form the next population.
Algorithm 4 shows the simple GA. Here, Select(P) returns a parent chosen from P by parent selection, Crossover(\mathbf{u}, \mathbf{v}) returns the offspring of \mathbf{u} and \mathbf{v} created by crossover, and Mutate(\mathbf{y}) returns a mutation of \mathbf{y}.
\begin{algorithm} \caption{Simple Genetic Algorithm} \begin{algorithmic} \Require population size $N$ \Ensure best solution found $\mathbf{x}_{\text{best}}$ \State generate an initial population $P$ \State evaluate $f(\mathbf{x})$ for all $\mathbf{x} \in P$ \State $\mathbf{x}_{\text{best}} \gets \arg\min_{\mathbf{x} \in P} f(\mathbf{x})$ \While{stopping criterion not met} \State $Q \gets$ an empty list for the offspring \ForAll{$i = 1, \ldots, N/2$} \State $\mathbf{u} \gets$ \textsc{Select}$(P)$, $\mathbf{v} \gets$ \textsc{Select}$(P)$ \State $(\mathbf{u}, \mathbf{v}) \gets$ \textsc{Crossover}$(\mathbf{u}, \mathbf{v})$ \State append \textsc{Mutate}$(\mathbf{u})$ and \textsc{Mutate}$(\mathbf{v})$ to $Q$ \EndFor \State $P \gets Q$ \State evaluate $f(\mathbf{x})$ for all $\mathbf{x} \in P$ \If{$\min_{\mathbf{x} \in P} f(\mathbf{x}) < f(\mathbf{x}_{\text{best}})$} \State $\mathbf{x}_{\text{best}} \gets \arg\min_{\mathbf{x} \in P} f(\mathbf{x})$ \EndIf \EndWhile \State \textbf{return} $\mathbf{x}_{\text{best}}$ \end{algorithmic} \end{algorithm}
The simple GA creates two offspring from each pair of parents, so the population size N should be even. Crossover is applied with a probability p_{\text{c}} called the crossover probability: with probability p_{\text{c}}, Crossover(\mathbf{u}, \mathbf{v}) returns two offspring created by crossover, and otherwise it returns copies of \mathbf{u} and \mathbf{v}. Each offspring is then mutated.
In the simple GA, the best solution in the population may be lost, because all N offspring can be worse than it. It can then no longer be selected as a parent, and the smallest value of f in the population increases. For this reason, Algorithm 4 stores the best solution found so far separately as \mathbf{x}_{\text{best}}.
31.4.2 Elitism
Elitism prevents this loss by passing the best solutions in the population, called elites, into the next population without change. Let k be the number of elites. Since the elites take k of the N places in the next population, the next population consists of the k best solutions in P and N - k offspring. With elitism, the smallest value of f in the population never increases, and the best solution found so far is always in the population.
A larger k keeps more good solutions, but, as with high selection pressure, the population may soon consist of copies of a few solutions.
Algorithm 5 shows the GA with elitism. Compared with SGA in Algorithm 4, the list Q starts with the elites instead of being empty, and \lceil (N - k)/2 \rceil pairs of offspring are appended to it, where \lceil z \rceil denotes z rounded up to an integer. If N - k is odd, Q then has N + 1 solutions, and the last offspring is discarded.
\begin{algorithm} \caption{Genetic Algorithm with Elitism} \begin{algorithmic} \Require population size $N$, number of elites $k$ \Ensure best solution found \State generate an initial population $P$ \State evaluate $f(\mathbf{x})$ for all $\mathbf{x} \in P$ \While{stopping criterion not met} \State $Q \gets$ a list of the $k$ best solutions in $P$ \ForAll{$i = 1, \ldots, \lceil (N - k)/2 \rceil$} \State $\mathbf{u} \gets$ \textsc{Select}$(P)$, $\mathbf{v} \gets$ \textsc{Select}$(P)$ \State $(\mathbf{u}, \mathbf{v}) \gets$ \textsc{Crossover}$(\mathbf{u}, \mathbf{v})$ \State append \textsc{Mutate}$(\mathbf{u})$ and \textsc{Mutate}$(\mathbf{v})$ to $Q$ \EndFor \State remove the last solution from $Q$ if $|Q| > N$ \State $P \gets Q$ \State evaluate $f(\mathbf{x})$ for all $\mathbf{x} \in P$ \EndWhile \State \textbf{return} $\arg\min_{\mathbf{x} \in P} f(\mathbf{x})$ \end{algorithmic} \end{algorithm}
31.5 Parallel Evaluation
Given P, the pairs of offspring do not depend on each other, so they can be created and evaluated in parallel. Population-based methods are therefore among the most readily parallelizable metaheuristics. Parallel evaluation is particularly useful when computing f takes a long time, for example when f(\mathbf{x}) is estimated by a simulation.
- https://github.com/RobertTLange/evosax
Local search and simulated annealing, in contrast, move from one solution to the next, and each move depends on the previous one.
31.6 Genetic Algorithm for the TSP
We apply the GA to the Car 54 instance of Chapter 29. The following code defines the instance in the same way as in Chapter 29.
Code
# Name, latitude, and longitude of each city
cities = [
    ("Chicago, IL", 41.8500, -87.6500),
    ("Indianapolis, IN", 39.7667, -86.1500),
    ("Marion, OH", 40.5833, -83.1167),
    ("Erie, PA", 42.1167, -80.0833),
    ("Carlisle, PA", 40.2000, -77.1833),
    ("Wana, WV", 39.7000, -80.2833),
    ("Wilkesboro, NC", 36.1500, -81.1333),
    ("Chattanooga, TN", 35.0333, -85.3000),
    ("Barnwell, SC", 33.2333, -81.3500),
    ("Bainbridge, GA", 30.9000, -84.5667),
    ("Baton Rouge, LA", 30.4500, -91.1500),
    ("Little Rock, AR", 34.7333, -92.2833),
    ("Kansas City, MO", 39.0833, -94.5667),
    ("La Crosse, WI", 43.8000, -91.2333),
    ("Blunt, SD", 44.5000, -99.9833),
    ("Lincoln, NE", 40.8000, -96.6667),
    ("Wichita, KS", 37.6833, -97.3333),
    ("Amarillo, TX", 35.2167, -101.8167),
    ("Truth or Consequences, NM", 33.1167, -107.2500),
    ("Manuelito, NM", 35.4167, -108.9833),
    ("Colorado Springs, CO", 38.8333, -104.8167),
    ("Butte, MT", 46.0000, -112.5333),
    ("Lewiston, ID", 46.4167, -117.0167),
    ("Boise, ID", 43.6000, -116.2000),
    ("Twin Falls, ID", 42.5500, -114.4500),
    ("Salt Lake City, UT", 40.7500, -111.8833),
    ("Mexican Hat, UT", 37.1500, -109.8500),
    ("Marble Canyon, AZ", 36.8000, -111.6333),
    ("Reno, NV", 39.5167, -119.8000),
    ("Lone Pine, CA", 36.6000, -118.0500),
    ("Gustine, CA", 37.2500, -120.9833),
    ("Redding, CA", 40.5833, -122.3833),
    ("Portland, OR", 45.5167, -122.6667),
]

# Road distances in miles. Row i lists the distances from city i
# to cities 0, 1, ..., i - 1 (the lower triangle of D).
lower_triangle = [
    [184],
    [292, 195],
    [449, 310, 215],
    [670, 540, 380, 288],
    [516, 357, 232, 200, 211],
    [598, 514, 434, 566, 436, 381],
    [618, 434, 493, 787, 814, 642, 295],
    [881, 697, 719, 790, 632, 697, 224, 320],
    [909, 964, 955, 1020, 974, 952, 541, 341, 318],
    [978, 892, 1031, 1246, 1352, 1180, 843, 538, 747, 441],
    [654, 597, 803, 1018, 1154, 1104, 766, 461, 749, 634, 380],
    [504, 503, 722, 937, 1043, 806, 986, 722, 1042, 954, 784, 404],
    [276, 460, 568, 725, 946, 817, 874, 894, 1214, 1185, 1218, 660, 452],
    [780, 964, 1072, 1229, 1450, 1321, 1378, 1326, 1646, 1672, 1410, 1030, 626, 476],
    [529, 644, 789, 1004, 1184, 1001, 1214, 950, 1270, 1213, 1043, 632, 219, 436, 419],
    [805, 698, 917, 1132, 1238, 1055, 1113, 842, 1162, 1027, 779, 473, 195, 637, 634,
     256],
    [1181, 1007, 1226, 1441, 1547, 1364, 1375, 1080, 1134, 1138, 783, 611, 563, 1046,
     759, 624, 368],
    [1548, 1444, 1630, 1845, 1984, 1801, 1726, 1431, 1685, 1477, 1134, 1033, 906, 1389,
     1094, 967, 711, 404],
    [1547, 1454, 1668, 1883, 1994, 1811, 1879, 1584, 1776, 1632, 1267, 1053, 944, 1427,
     1196, 1005, 749, 442, 251],
    [1239, 1167, 1353, 1568, 1707, 1524, 1584, 1313, 1633, 1498, 1151, 979, 614, 988,
     600, 525, 471, 368, 512, 507],
    [1538, 1733, 1830, 2045, 2208, 2090, 2136, 2078, 2398, 2332, 2110, 1782, 1378, 1300,
     760, 1229, 1382, 1319, 1163, 930, 910],
    [1999, 2158, 2291, 2448, 2669, 2515, 2597, 2500, 2820, 2675, 2336, 2164, 1707, 1860,
     1375, 1582, 1658, 1545, 1389, 1156, 1237, 436],
    [1716, 1875, 2008, 2165, 2386, 2232, 2488, 2217, 2537, 2392, 2053, 1881, 1422, 1577,
     1106, 1244, 1375, 1262, 1106, 873, 954, 483, 283],
    [1580, 1738, 1872, 2029, 2250, 2095, 2352, 2081, 2401, 2256, 1917, 1745, 1286, 1473,
     988, 1147, 1239, 1126, 970, 737, 818, 379, 419, 136],
    [1425, 1569, 1717, 1874, 2109, 1926, 2115, 1844, 2164, 2019, 1680, 1508, 1118, 1335,
     862, 913, 1002, 889, 733, 500, 581, 430, 656, 373, 237],
    [1560, 1549, 1852, 2009, 2089, 1906, 2063, 1792, 2112, 1967, 1456, 1274, 1032, 1540,
     1068, 1007, 944, 665, 521, 282, 491, 768, 994, 711, 575, 358],
    [1918, 1744, 1963, 2178, 2284, 2101, 2174, 1879, 2071, 1892, 1562, 1348, 1239, 1722,
     1258, 1300, 1044, 737, 526, 295, 802, 816, 1022, 739, 603, 386, 545],
    [2065, 2102, 2357, 2514, 2642, 2459, 2626, 2355, 2675, 2530, 2191, 2019, 1673, 1905,
     1432, 1570, 1507, 1320, 1109, 878, 1124, 842, 715, 432, 465, 533, 849, 739],
    [2284, 2131, 2326, 2441, 2671, 2488, 2418, 2133, 2437, 2259, 1929, 1715, 1606, 1924,
     1451, 1589, 1411, 1104, 893, 662, 1143, 1004, 981, 698, 599, 589, 768, 523, 266],
    [2340, 2348, 2543, 2658, 2888, 2705, 2869, 2598, 2918, 2773, 2434, 2262, 1916, 2148,
     1675, 1813, 1750, 1468, 1102, 871, 1367, 1085, 958, 675, 1033, 778, 1092, 982, 243,
     349],
    [2247, 2327, 2539, 2696, 2867, 2684, 2851, 2580, 2900, 2755, 2416, 2244, 1898, 2130,
     1657, 1795, 1732, 1545, 1334, 1103, 1349, 1014, 814, 531, 1015, 760, 1047, 964,
     225, 497, 266],
    [2163, 2322, 2455, 2612, 2833, 2679, 2761, 2664, 2984, 2839, 2500, 2328, 1871, 2024,
     1539, 1746, 1822, 1709, 1553, 1320, 1391, 693, 346, 447, 583, 820, 1158, 1355, 581,
     847, 710, 444],
]

n = len(cities)
D = np.zeros((n, n), dtype=int)
for i, row in enumerate(lower_triangle, start=1):
    D[i, :i] = row
D = D + D.T

# The optimal tour reported by Karg and Thompson (1964)
optimal_tour = [0, 1, 2, 3, 5, 4, 6, 8, 7, 9, 10, 11, 12, 15, 16, 17, 18,
                19, 27, 29, 28, 30, 31, 32, 22, 23, 24, 21, 25, 26, 20, 14, 13]
optimal_length = tour_length(optimal_tour, D)
The function genetic_algorithm() follows Algorithm 5 with tournament selection, order crossover with random cut points, and inversion mutation. Each pair of offspring is created with the same cut points by exchanging the roles of the parents. The argument n_elites is the number of elites k. The function stops after n_generations generations and returns the best tour found. For each generation, it also records in history the shortest and average tour lengths and the number of distinct tours in the population. The argument mutation is used in Exercise 31.4, and no_duplicates in Section 31.7.
def genetic_algorithm(
    D, pop_size, n_elites, n_generations, t, p_mut, rng,
    mutation=inversion_mutation, no_duplicates=False,
):
    """GA for the TSP with tournament selection, order crossover, and elitism.
    If no_duplicates is True, an offspring that is already in the next
    population is discarded without being evaluated.
    Return the best tour found and, for each generation, the shortest and
    average tour lengths and the number of distinct tours in the population."""
    n = len(D)
    population = [rng.permutation(n).tolist() for _ in range(pop_size)]
    lengths = [tour_length(tour, D) for tour in population]
    history = [(min(lengths), np.mean(lengths), len({tuple(t) for t in population}))]
    for _ in range(n_generations):
        # Elites: the n_elites shortest tours in the population
        elites = sorted(range(pop_size), key=lambda i: lengths[i])[:n_elites]
        elite_tours = [population[i] for i in elites]
        elite_lengths = [lengths[i] for i in elites]
        offspring = []
        seen = {tuple(tour) for tour in elite_tours}  # tours in the next population
        while len(offspring) < pop_size - n_elites:  # pairs of offspring
            u = population[tournament_selection(lengths, t, rng)]
            v = population[tournament_selection(lengths, t, rng)]
            a, b = sorted(rng.choice(n + 1, size=2, replace=False))  # cut points
            for y in (order_crossover(u, v, a, b), order_crossover(v, u, a, b)):
                if rng.random() < p_mut:
                    y = mutation(y, rng)
                if no_duplicates and tuple(y) in seen:
                    continue  # discard a duplicate without evaluating it
                seen.add(tuple(y))
                offspring.append(y)
        offspring = offspring[: pop_size - n_elites]  # discard an extra offspring
        offspring_lengths = [tour_length(y, D) for y in offspring]
        population = elite_tours + offspring  # elitism
        lengths = elite_lengths + offspring_lengths
        history.append(
            (min(lengths), np.mean(lengths), len({tuple(t) for t in population}))
        )
    i = int(np.argmin(lengths))
    return population[i], history
We use a population of N = 100 tours, the tournament size t = 3, and the mutation probability p_{\text{m}} = 0.1. These values were chosen after a few trial runs. With one elite, k = 1, each generation creates 50 pairs of offspring and discards one offspring, so it evaluates N - k = 99 new tours, and 500 generations evaluate 49,500 new tours, as many as the neighbors that simulated annealing evaluates in Section 30.2.
rng = np.random.default_rng(0)
pop_size, n_elites, n_generations, t, p_mut = 100, 1, 500, 3, 0.1
best_tour, history = genetic_algorithm(
    D, pop_size, n_elites, n_generations, t, p_mut, rng
)

print(f"Genetic algorithm: {tour_length(best_tour, D):,} miles")
print(f"Optimal tour:      {optimal_length:,} miles")
Genetic algorithm: 11,388 miles
Optimal tour: 10,861 milesFigure 31.4 shows how the population changes during this run. In the first 100 generations, the shortest tour length in the population falls from 33,391 to 13,262 miles. In the same period, the number of distinct tours in the population falls from 100 to 36, because selection and crossover fill the population with copies of a few good tours. When both parents are the same tour, order crossover returns two copies of that tour, so such a population produces few new tours. The shortest tour length improves 20 more times by generation 215 and then stays at 11,388 miles for the remaining 285 generations. From generation 225 on, the population contains at most 21 distinct tours.
Code
import matplotlib.pyplot as plt
from matplotlib.ticker import StrMethodFormatter

shortest, average, n_distinct = zip(*history)

fig, (ax1, ax2) = plt.subplots(
    2, 1, figsize=(6, 5), sharex=True, gridspec_kw={"height_ratios": [2, 1]}
)
ax1.plot(average, color="gray", linewidth=1, label="Average")
ax1.plot(shortest, color="black", linewidth=1.5, label="Shortest")
ax1.axhline(optimal_length, color="black", linestyle=":", linewidth=1)
ax1.text(n_generations, optimal_length, "Optimal", va="bottom", ha="right")
ax1.set_ylim(10_500, 16_000)
ax1.set_ylabel("Tour length (miles)")
ax1.yaxis.set_major_formatter(StrMethodFormatter("{x:,.0f}"))
ax1.legend(frameon=False)

ax2.plot(n_distinct, color="black", linewidth=1)
ax2.set_ylim(0, 105)
ax2.set_xlabel("Generation")
ax2.set_ylabel("Distinct tours")
for ax in (ax1, ax2):
    ax.spines[["top", "right"]].set_visible(False)
fig.tight_layout()
plt.show()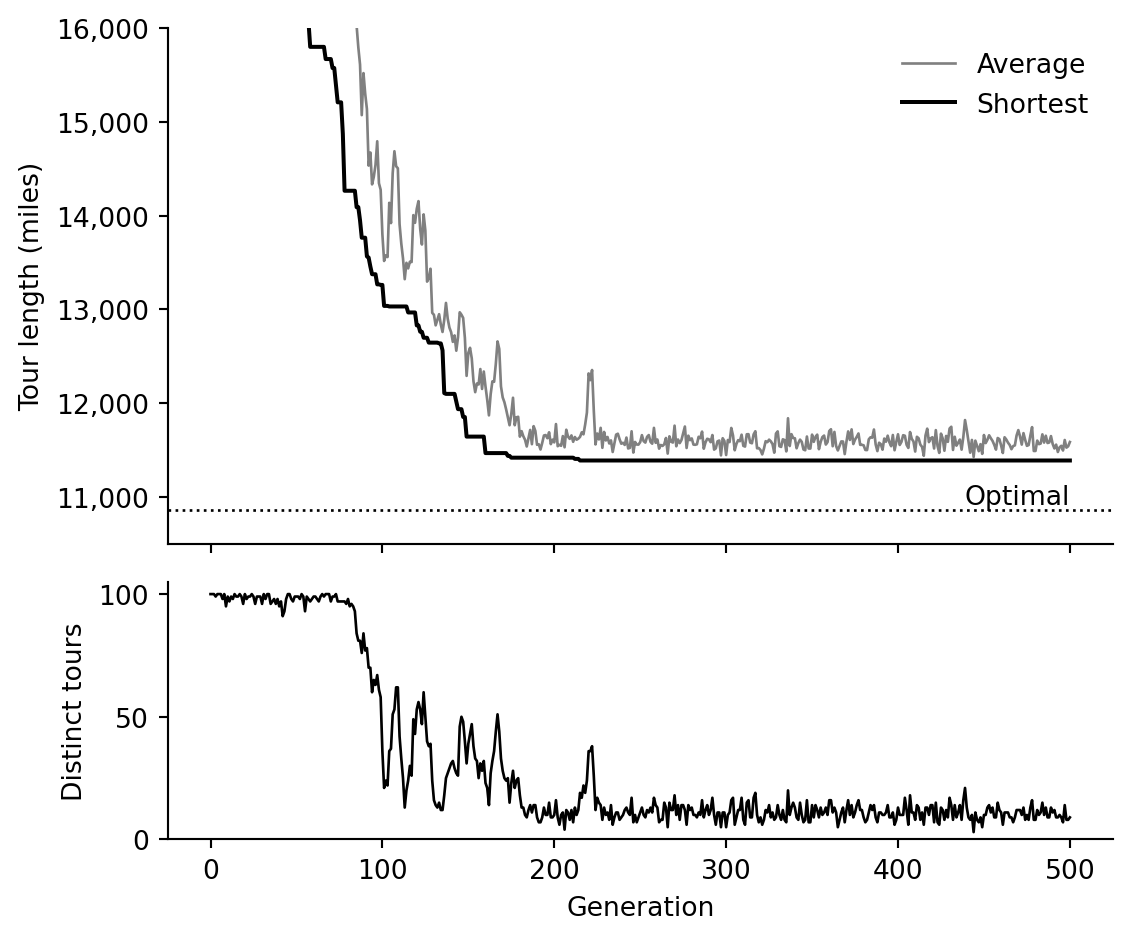
The best tour found in this run is a local optimum with respect to the 2-opt neighborhood: local search starting from it makes no move.
_, lengths = local_search(best_tour, D, first_improvement)
print(f"Moves made by local search: {len(lengths) - 1}")
Moves made by local search: 0Since inversion mutation is a 2-opt exchange chosen at random, mutating this tour cannot make it shorter. The GA has thus reached the same kind of solution as local search: a local optimum that is not optimal.
The GA makes random choices, so another run may return a different tour. The following code runs the GA 100 times.
n_runs = 100
rng = np.random.default_rng(0)
ga_lengths = []
for _ in range(n_runs):
    best_tour, _ = genetic_algorithm(
        D, pop_size, n_elites, n_generations, t, p_mut, rng
    )
    ga_lengths.append(tour_length(best_tour, D))

print(f"Optimal in {ga_lengths.count(optimal_length)} of {n_runs} runs")
print(f"Average length: {np.mean(ga_lengths):,.0f} miles")
print(f"Longest length: {max(ga_lengths):,} miles")
Optimal in 8 of 100 runs
Average length: 11,218 miles
Longest length: 12,189 milesFollowing Eiben and Smith (2015, sec. 9.2.1), we report two measures: the success rate, that is, the fraction of runs that find an optimal tour, and the average length of the best tours found. The GA finds an optimal tour in 8 of the 100 runs, and the average length is 11,218 miles, 3.3% above the optimal length. An algorithm whose success rate is low but whose average is good is called a good approximizer (Eiben and Smith 2015, sec. 9.2.1): it gets close to the optimum but seldom reaches it.
In Section 30.2, simulated annealing evaluated the same number of tours per run and found an optimal tour in 35 of 100 runs, and local search found an optimal tour in 12 of 100 runs, with an average length of 11,190 miles. On this instance, the GA thus does no better than a single local search, which stops after evaluating far fewer neighbors. This comparison holds for this instance with these operators and parameter values; Exercise 31.4 shows that other choices can give much worse results.
31.7 Avoiding Duplicates
One reason why the GA does no better than local search can be seen in Figure 31.4. From generation 225 on, the population contains at most 21 distinct tours, so in each of these generations, at least 79 of the 99 new tours are copies of other tours in the population. The length of a copy is already known, so evaluating it gives no new information.
A common way to keep the population diverse is a no-duplicates policy, which does not allow copies of the same solution in the population. We add it to Algorithm 5 as follows: an offspring that is already in Q is discarded without being evaluated, so more pairs of offspring may be needed to fill Q. In genetic_algorithm(), this policy is used when no_duplicates is True.
The following code runs the GA 100 times with the no-duplicates policy and the other settings unchanged.
rng = np.random.default_rng(0)
no_duplicate_lengths = []
for _ in range(n_runs):
    best_tour, _ = genetic_algorithm(
        D, pop_size, n_elites, n_generations, t, p_mut, rng, no_duplicates=True
    )
    no_duplicate_lengths.append(tour_length(best_tour, D))

print(f"Optimal in {no_duplicate_lengths.count(optimal_length)} of {n_runs} runs")
print(f"Average length: {np.mean(no_duplicate_lengths):,.0f} miles")
print(f"Longest length: {max(no_duplicate_lengths):,} miles")
Optimal in 30 of 100 runs
Average length: 11,001 miles
Longest length: 12,142 milesWith the no-duplicates policy, the GA finds an optimal tour in 30 of the 100 runs, compared with 8 without it, and the average length falls from 11,218 to 11,001 miles, 1.3% above the optimal length. Since the population contains no copies, the two parents are almost always different, and crossover keeps creating new tours. Each run still evaluates 49,500 tours, because discarded offspring are not evaluated, although creating them takes time. With the same number of evaluated tours, simulated annealing found an optimal tour in 35 runs, with an average length of 10,938 miles. The GA now finds an optimal tour almost as often, although its average length is longer.
31.8 Genetic Algorithm with Local Search
The best tour found in the run of Figure 31.4 is a 2-opt local optimum, and multi-start local search finds many local optima independently of each other. A natural combination is to apply local search to every offspring: crossover combines two local optima, and local search turns the offspring into a local optimum again. Such combinations of evolutionary algorithms and local search are called memetic algorithms (Moscato 1989; Eiben and Smith 2015, chap. 10) or genetic local search (Kochenderfer and Wheeler 2019, sec. 9.7).
The function genetic_local_search() below modifies Algorithm 5 with k = 1 in two ways. First, every initial tour and every offspring is replaced by the local optimum found by the first-improvement local search of Chapter 29. Replacing a solution by the result of local search in this way is called Lamarckian learning (Kochenderfer and Wheeler 2019, sec. 9.7). Second, mutation is not used, because local search already changes the offspring.
Both genetic local search and multi-start local search spend almost all of their time in local search. To compare them fairly, we give both the same budget, measured by the number of neighbors evaluated, that is, the number of calls to delta(). The following code redefines delta() so that it also counts its calls in the global variable n_evaluations. The function first_improvement() then calls the new delta() without any change. The function multi_start_local_search() follows the multi-start local search of Chapter 29, but it stops when the budget is used up instead of after R starts. Both functions check the budget before each local search, so the last local search may exceed it slightly.
n_evaluations = 0  # number of calls to delta()


def delta(tour, i, j, D):
    """Change in the tour length caused by two_opt_move(tour, i, j).
    Also count the call in n_evaluations."""
    global n_evaluations
    n_evaluations += 1
    n = len(tour)
    a, b = tour[i], tour[i + 1]
    c, d = tour[j], tour[(j + 1) % n]
    return D[a, c] + D[b, d] - D[a, b] - D[c, d]


def multi_start_local_search(D, budget, rng):
    """Multi-start local search (first improvement) from random tours.
    Stop when the local searches have evaluated budget neighbors."""
    global n_evaluations
    n_evaluations = 0
    best_tour, best_length = None, float("inf")
    while n_evaluations < budget:
        tour, lengths = local_search(
            rng.permutation(len(D)).tolist(), D, first_improvement
        )
        if lengths[-1] < best_length:
            best_tour, best_length = tour, lengths[-1]
    return best_tour, best_length


def genetic_local_search(D, pop_size, t, budget, rng):
    """GA in which every initial tour and every offspring is replaced by the
    local optimum found by local search (first improvement), without mutation.
    Stop when the local searches have evaluated budget neighbors."""
    global n_evaluations
    n_evaluations = 0
    n = len(D)
    population = [
        local_search(rng.permutation(n).tolist(), D, first_improvement)[0]
        for _ in range(pop_size)
    ]
    lengths = [tour_length(tour, D) for tour in population]
    i = int(np.argmin(lengths))
    best_tour, best_length = population[i], lengths[i]
    while n_evaluations < budget:
        new_population, new_lengths = [best_tour], [best_length]  # elitism
        while len(new_population) < pop_size and n_evaluations < budget:
            u = population[tournament_selection(lengths, t, rng)]
            v = population[tournament_selection(lengths, t, rng)]
            a, b = sorted(rng.choice(n + 1, size=2, replace=False))
            for y in (order_crossover(u, v, a, b), order_crossover(v, u, a, b)):
                if len(new_population) == pop_size or n_evaluations >= budget:
                    break  # discard an extra offspring
                y, y_lengths = local_search(y, D, first_improvement)
                new_population.append(y)
                new_lengths.append(y_lengths[-1])
        population, lengths = new_population, new_lengths
        i = int(np.argmin(lengths))
        best_tour, best_length = population[i], lengths[i]
    return best_tour, best_length
We give each method a budget of 200,000 neighbor evaluations and run it 100 times. For genetic local search, we use a population of N = 10 tours and the tournament size t = 3.
budget = 200_000
methods = {
    "Multi-start local search": lambda rng: multi_start_local_search(D, budget, rng),
    "Genetic local search": lambda rng: genetic_local_search(D, 10, t, budget, rng),
}
for name, method in methods.items():
    rng = np.random.default_rng(0)
    results, evaluations = [], []
    for _ in range(n_runs):
        _, length = method(rng)
        results.append(length)
        evaluations.append(n_evaluations)
    print(
        f"{name:25} optimal in {results.count(optimal_length):2} runs, "
        f"average {np.mean(results):,.0f} miles, "
        f"{np.mean(evaluations):,.0f} neighbors evaluated"
    )
With the same budget, genetic local search finds an optimal tour in 93 of the 100 runs, compared with 79 for multi-start local search, and its average length is shorter (10,865 versus 10,875 miles). Both methods use about the same number of neighbor evaluations. Multi-start local search uses slightly more, because its last local search, which starts from a random tour, exceeds the budget by more.
One reason for the difference is that an offspring of two local optima inherits many edges from its parents, so local search from an offspring is short. The following code compares the number of neighbors evaluated by local search from a random tour and from an offspring of two local optima.
rng = np.random.default_rng(1)
local_optima = [
    local_search(rng.permutation(n).tolist(), D, first_improvement)[0]
    for _ in range(10)
]
from_random, from_offspring = [], []
for _ in range(100):
    n_evaluations = 0
    local_search(rng.permutation(n).tolist(), D, first_improvement)
    from_random.append(n_evaluations)

    i, j = rng.choice(len(local_optima), size=2, replace=False)
    a, b = sorted(rng.choice(n + 1, size=2, replace=False))
    n_evaluations = 0
    local_search(
        order_crossover(local_optima[i], local_optima[j], a, b), D, first_improvement
    )
    from_offspring.append(n_evaluations)

print(f"From a random tour:  {np.mean(from_random):,.0f} neighbors on average")
print(f"From an offspring:   {np.mean(from_offspring):,.0f} neighbors on average")
From a random tour: 12,406 neighbors on average
From an offspring: 2,408 neighbors on averageA local search from an offspring evaluates about one fifth as many neighbors as a local search from a random tour. Within the same budget, genetic local search can therefore perform many more local searches than multi-start local search, and each local search from an offspring starts from a combination of two good tours rather than from a random tour.
31.9 Binary Representation
When the decision variables are binary, as in the 0-1 knapsack problem of Exercise 29.3, a solution is a vector \mathbf{x} = (x_1, \ldots, x_m) \in \{0, 1\}^m. Binary vectors are the representation of the simple GA, the classical form of the GA (Eiben and Smith 2015, sec. 6.1).
The simplest crossover is one-point crossover (Luke 2013, sec. 3.2.1). It chooses a cut point c \in \{1, \ldots, m - 1\} and joins the first c components of \mathbf{u} with the last m - c components of \mathbf{v}:
\mathbf{y} = (u_1, \ldots, u_c, v_{c+1}, \ldots, v_m).
For binary vectors, any combination of components is a valid vector, so the offspring is always a binary vector.
Example 31.3 (One-point crossover) Consider the binary vectors \mathbf{u} = (1, 0, 1, 1, 0, 0) and \mathbf{v} = (0, 1, 1, 0, 1, 1) with the cut point c = 3 (Figure 31.5). One-point crossover gives \mathbf{y} = (1, 0, 1, 0, 1, 1).
def one_point_crossover(u, v, c):
    """Join the first c components of u with the remaining components of v."""
    return u[:c] + v[c:]


print(one_point_crossover([1, 0, 1, 1, 0, 0], [0, 1, 1, 0, 1, 1], 3))
[1, 0, 1, 0, 1, 1]Code
import matplotlib.patches as mpatches


def draw_one_point_crossover(ax, u, v, c):
    """Draw u, v, and their offspring by one-point crossover with the cut point c."""
    y = one_point_crossover(u, v, c)
    m, gap = len(u), 0.3  # gap: horizontal gap at the cut point
    rows = [  # label, components, fill colors, bottom of the row
        (r"$\mathbf{u}$", u, ["white"] * m, 2.9),
        (r"$\mathbf{v}$", v, ["lightgray"] * m, 1.65),
        (r"$\mathbf{y}$", y, ["white"] * c + ["lightgray"] * (m - c), 0),
    ]
    for label, row, fills, bottom in rows:
        ax.text(-0.3, bottom + 0.5, label, ha="right", va="center", fontsize=12)
        for j, (value, fill) in enumerate(zip(row, fills)):
            left = j + (gap if j >= c else 0)
            ax.add_patch(
                mpatches.Rectangle(
                    (left, bottom), 1, 1, facecolor=fill, edgecolor="black", linewidth=1
                )
            )
            ax.text(
                left + 0.5, bottom + 0.5, str(value), ha="center", va="center", fontsize=12
            )
    ax.plot([c + gap / 2] * 2, [-0.3, 4.2], color="black", linestyle="--", linewidth=1)
    ax.text(c + gap / 2, 4.3, f"$c = {c}$", ha="center", va="bottom", fontsize=11)
    ax.set(xlim=(-0.9, m + gap + 0.1), ylim=(-0.4, 4.8), aspect="equal")
    ax.axis("off")


fig, ax = plt.subplots(figsize=(4, 2.9))
draw_one_point_crossover(ax, [1, 0, 1, 1, 0, 0], [0, 1, 1, 0, 1, 1], 3)
fig.tight_layout()
plt.show()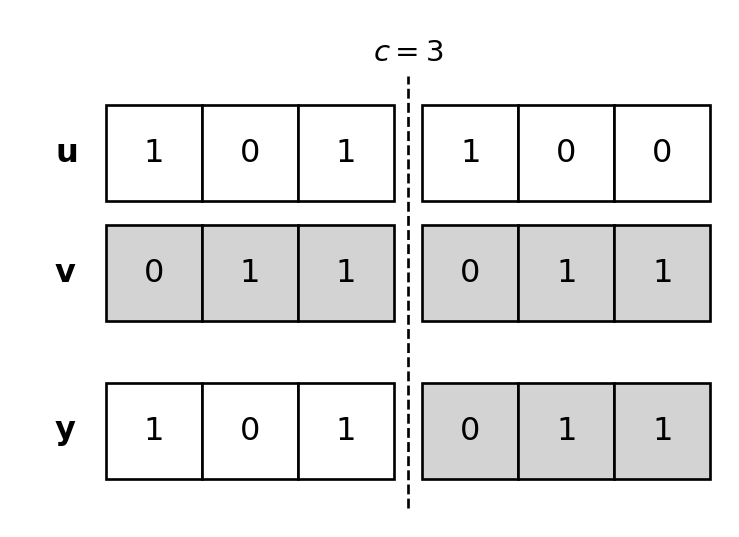
Other common operators are the following (Luke 2013, sec. 3.2.1; Kochenderfer and Wheeler 2019, sec. 9.2):
- Two-point crossover chooses two cut points and takes the components between them from \mathbf{v} and the other components from \mathbf{u}.
- Uniform crossover takes each component from \mathbf{u} or \mathbf{v} with probability 1/2. The second offspring takes each component from the other parent.
- Bit-flip mutation flips each component independently with probability p. A common choice is p = 1/m, which flips one component on average (Kochenderfer and Wheeler 2019, sec. 9.2.3). Here, every offspring is mutated, that is, p_{\text{m}} = 1 in Algorithm 5, and p controls the size of the change.
def uniform_crossover(u, v, rng):
    """Return two offspring. The first takes each component from u or v with
    probability 1/2, and the second takes it from the other parent."""
    from_u = [rng.random() < 0.5 for _ in u]
    y = [ui if m else vi for ui, vi, m in zip(u, v, from_u)]
    z = [vi if m else ui for ui, vi, m in zip(u, v, from_u)]
    return y, z


def bit_flip_mutation(x, p, rng):
    """Flip each component independently with probability p."""
    return [1 - xi if rng.random() < p else xi for xi in x]


rng = np.random.default_rng(0)
u, v = [1] * 8, [0] * 8
print(one_point_crossover(u, v, 3))
print(uniform_crossover(u, v, rng))
print(bit_flip_mutation(u, 1 / 8, rng))
[1, 1, 1, 0, 0, 0, 0, 0]
([0, 1, 1, 1, 0, 0, 0, 0], [1, 0, 0, 0, 1, 1, 1, 1])
[1, 1, 1, 0, 1, 0, 1, 1]Unlike a permutation for the TSP, a binary vector may violate the constraints of the problem. In the knapsack problem, for example, an offspring may exceed the capacity of the knapsack. Such offspring can be handled by a penalty function or by a repair method (Chapter 35), as in Exercise 31.5.
For continuous decision variables, GAs use other operators, such as simulated binary crossover (Deb and Agrawal 1995). In this book, problems with continuous variables are solved by differential evolution (Chapter 33) and particle swarm optimization (Chapter 32).
31.11 Exercises
Exercise 31.1 (Order Crossover by Hand) Consider the parents \mathbf{u} = (1, 2, 3, 4, 5, 6, 7, 8) and \mathbf{v} = (2, 4, 6, 8, 7, 5, 3, 1) and the cut points a = 2 and b = 5.
- Apply order crossover to obtain the offspring \mathbf{y}. Then exchange the roles of \mathbf{u} and \mathbf{v} to obtain the second offspring.
- List the edges of the tour \mathbf{y}. Which edges belong to \mathbf{u}, which belong to \mathbf{v}, and which belong to neither parent?
- Using your answer to question 2, explain why order crossover may not be well suited to the TSP.
Exercise 31.2 (Selection Probabilities in Tournament Selection) Consider a population of N solutions \mathbf{x}_1, \ldots, \mathbf{x}_{N} with f(\mathbf{x}_1) < f(\mathbf{x}_2) < \cdots < f(\mathbf{x}_{N}), so that \mathbf{x}_r is the rth best solution. Tournament selection chooses t solutions at random with replacement.
- Show that \mathbf{x}_r is selected with probability q_r = \left(\frac{N - r + 1}{N}\right)^t - \left(\frac{N - r}{N}\right)^t. (Hint: When does the selected solution have rank r or larger?)
- For N = 100, compute q_1 and q_{100} for t = 1, 2, and 3. In one generation of the GA in Section 31.6, tournament selection is used 2 \times 50 = 100 times. How many times is the best solution selected on average?
- Show that the selection probabilities do not change if f is replaced by g \circ f for a strictly increasing function g. Does the same hold for fitness-proportional selection with F_i = f_{\max} - f(\mathbf{x}_i)?
Exercise 31.3 (Fitness-Proportional Selection) Consider a population of four tours with lengths 11,000, 11,500, 12,000, and 40,000 miles, and fitness-proportional selection with F_i = f_{\max} - f(\mathbf{x}_i).
- Compute the selection probabilities of the four tours.
- Remove the tour of 40,000 miles, and compute the selection probabilities of the other three tours.
- Compare your answers to questions 1 and 2. How does a single very bad tour affect the selection pressure?
- Compute the selection probabilities in tournament selection with t = 3 for both populations, using Exercise 31.2.
Exercise 31.4 (Operators and Parameters) The results of the GA in Section 31.6 depend on its operators and parameters.
- Run the GA 20 times with swap mutation instead of inversion mutation, by passing
mutation=swap_mutationtogenetic_algorithm(), and with the other settings unchanged. Compare the number of runs that find an optimal tour and the average length with those in Section 31.6, and explain the difference using Example 31.2. - Run the GA 20 times with the tournament size t = 2 and the other settings of Section 31.6. Compare the results with those in Section 31.6, and explain the difference. (Hint: Look at the shortest and average tour lengths and the number of distinct tours in the population, as in Figure 31.4.)
Exercise 31.5 (A GA for the 0-1 Knapsack Problem) Consider the 0-1 knapsack problem of Exercise 29.3 with n = 50 items. The following code generates the weights w_j and the values c_j as random integers between 1 and 100, and sets the capacity K to half of the total weight.
rng = np.random.default_rng(0)
n_items = 50
weights = rng.integers(1, 101, size=n_items).tolist()
values = rng.integers(1, 101, size=n_items).tolist()
capacity = sum(weights) // 2- An offspring created by uniform crossover and bit-flip mutation may exceed the capacity. Propose a repair method that turns such an offspring into a feasible solution.
- Implement a GA with the binary representation, tournament selection with t = 3, uniform crossover, bit-flip mutation with p = 1/n, elitism, and your repair method. Run it 20 times with N = 50 and 100 generations.
- Compute the optimal value by dynamic programming (Chapter 15), and compare it with the results of your GA.