2 Markov Decision Processes
Markov decision processes (MDPs) are idealized models of reinforcement learning problems. In this chapter, we assume that complete knowledge of the environment’s dynamics is available.
2.1 Agent-Environment Interface
MDPs are used to formulate sequential decision-making problems. The agent interacts with the environment to achieve a goal.
- Agent: The learner and decision-maker
- Environment: Everything outside the agent

The agent interacts with the environment in discrete time t = 0, 1, 2, \ldots. At each time step t, the agent receives a representation of the environment’s state S_t \in \mathcal{S}, selects an action A_t \in \mathcal{A}(S_t), and receives a reward R_{t+1} \in \mathcal{R} \subset \mathbb{R} and the next state S_{t+1}.
The interaction between the agent and the environment can be summarized as a trajectory:
S_0, A_0, R_1, S_1, A_1, R_2, S_2, A_2, R_3, \ldots
2.2 Formulation of MDP
A Markov decision process (MDP) is a tuple (\mathcal{S}, \mathcal{A}, p, r, \gamma) where:
- \mathcal{S}: Set of states
- \mathcal{A}: Set of actions
- p(s', r | s, a): Dynamics function p: \mathcal{S} \times \mathcal{R} \times \mathcal{S} \times \mathcal{A} \rightarrow [0, 1]
- r(s, a): Reward function r: \mathcal{S} \times \mathcal{A} \rightarrow \mathbb{R}
- \gamma: Discount factor \gamma \in [0, 1]
2.2.1 Dynamics Function
The dynamics function p defines the probability of transitioning to state s' and receiving reward r given state s and action a.
p(s', r | s, a) = \Pr\{S_{t} = s', R_{t} = r | S_{t-1} = s, A_{t-1} = a\}
The state has the Markov property if the state includes all relevant information from the interaction history that may affect the future.
Note that p captures all the environment’s dynamics completely. The probability of each possible value of S_t and R_t depends only on the preceding state S_{t-1} and action A_{t-1}.
From p, we can also obtain the state-transition probability, which is the probability of transitioning to state s' given state s and action a:
p(s' | s, a) = \Pr\{S_{t} = s' | S_{t-1} = s, A_{t-1} = a\} = \sum_{r \in \mathcal{R}} p(s', r | s, a)
2.2.2 Reward Function
The reward function r(s, a) defines the expected reward given state s and action a.
\begin{align*} r(s, a) &= \mathbb{E}[R_{t} | S_{t-1} = s, A_{t-1} = a] \\ &= \sum_{r \in \mathcal{R}} r \sum_{s' \in \mathcal{S}} p(s', r | s, a) \end{align*}
2.2.3 Return
The objective of the agent is to maximize the expected value of the cumulative sum of a received scalar signal (reward).
To formalize the objective, we define the return G_t as a certain function of the rewards received after time t. The simplest form of return is the sum of rewards:
G_t = R_{t+1} + R_{t+2} + R_{t+3} + \ldots + R_T
where T is the final time step. Note that this definition of return is suitable for tasks that will eventually end. In such cases, each episode ends in a terminal state. Such tasks are called episodic tasks.
There are also MDPs that do not have terminal states. We call such MDPs continuing tasks. In continuing tasks, the return that we defined above could be infinite. To handle such cases, we introduce the concept of discounted return, which is defined as follows:
\begin{align*} G_t &= R_{t+1} + \gamma R_{t+2} + \gamma^2 R_{t+3} + \ldots \\ &= \sum_{k=0}^{\infty} \gamma^k R_{t+k+1} \end{align*}
where \gamma is the discount factor that satisfies 0 \leq \gamma \leq 1. If \gamma < 1 and the rewards are bounded, the infinite sum has a finite value.
The discounted return can be written in the following recursive form:
\begin{align*} G_t &= R_{t+1} + \gamma R_{t+2} + \gamma^2 R_{t+3} + \ldots \\ &= R_{t+1} + \gamma (R_{t+2} + \gamma R_{t+3} + \ldots) \\ &= R_{t+1} + \gamma G_{t+1} \end{align*}
2.3 Policy and Value Function
2.3.1 Policy
The agent interacts with the environment by selecting actions. To describe the agent’s behavior, we introduce the concept of policy. A policy is a mapping from states to probabilities of selecting each possible action. A policy is denoted by \pi.
\pi(a | s) = \Pr\{A_t = a | S_t = s\}
2.3.2 Value Function
The value function is the expected return when starting in state s and following policy \pi thereafter. The state-value function for policy \pi is denoted by v_{\pi}(s).
v_{\pi}(s) = \mathbb{E}_{\pi}[G_t | S_t = s]
Similarly, we use an action-value function to represent the expected return when starting in state s, taking action a, and following policy \pi thereafter. The action-value function for policy \pi is denoted by q_{\pi}(s, a).
q_{\pi}(s, a) = \mathbb{E}_{\pi}[G_t | S_t = s, A_t = a]
An important property of value functions is that they satisfy recursive relationships. The value of a state can be expressed in terms of the values of its possible successor states:
\begin{align*} v_{\pi}(s) &= \mathbb{E}_{\pi}[G_t | S_t = s] \\ &= \mathbb{E}_{\pi}[R_{t+1} + \gamma G_{t+1} | S_t = s] \\ &= \sum_{a} \pi(a|s) \sum_{s', r} p(s', r | s, a) [r + \gamma \mathbb{E}_{\pi}[G_{t+1} | S_{t+1} = s']] \\ &= \sum_{a} \pi(a|s) \sum_{s', r} p(s', r | s, a) [r + \gamma v_{\pi}(s')] \end{align*}
The last equation is known as the Bellman equation.
v_{\pi}(s) = \sum_{a} \pi(a|s) \sum_{s', r} p(s', r | s, a) [r + \gamma v_{\pi}(s')]
It is written in a recursive form that indicates the relationship between v_{\pi}(s) and the values v_{\pi}(s') of all possible successor states.
2.4 Optimal Policies and Optimal Value Functions
A policy \pi is better than or equal to a policy \pi', denoted by \pi \geq \pi', if v_{\pi}(s) \geq v_{\pi'}(s) for all s \in \mathcal{S}. There is always at least one policy that is better than or equal to all other policies. Such a policy is called an optimal policy and is denoted by \pi_*.
Using the concept of optimal policy, we can define the optimal state-value function and optimal action-value function as follows:
v_*(s) = \max_{\pi} v_{\pi}(s), \quad \forall s \in \mathcal{S}
q_*(s, a) = \max_{\pi} q_{\pi}(s, a), \quad \forall s \in \mathcal{S}, a \in \mathcal{A}
2.5 Bellman Optimality Equation
Because v_* is the value function of a policy, it must satisfy the Bellman equation. Since the policy is optimal, the value of a state under \pi_* must equal the expected return for the best action from that state:
\begin{align*} v_*(s) &= \max_{a} q_*(s, a) \\ &= \max_{a} \mathbb{E}_{\pi_*}[G_t | S_t = s, A_t = a] \\ &= \max_{a} \mathbb{E}_{\pi_*}[R_{t+1} + \gamma G_{t+1} | S_t = s, A_t = a] \\ &= \max_{a} \mathbb{E}[R_{t+1} + \gamma v_*(S_{t+1}) | S_t = s, A_t = a] \\ &= \max_{a} \sum_{s', r} p(s', r | s, a) [r + \gamma v_*(s')] \end{align*}
The last equation is known as the Bellman optimality equation.
v_*(s) = \max_{a} \sum_{s', r} p(s', r | s, a) [r + \gamma v_*(s')]
The Bellman optimality equation is a system of nonlinear equations. The solution to the system of equations is the optimal value function. For a finite MDP that has n states, the system of equations has n equations and n unknowns.
In addition, the Bellman optimality equation for the action-value function is:
q_*(s, a) = \sum_{s', r} p(s', r | s, a) [r + \gamma \max_{a'} q_*(s', a')]
Note that if we know the optimal value function v_*(s), for all s \in \mathcal{S}, we can easily find the optimal policy \pi_*(s) by selecting the action that maximizes the right-hand side of the Bellman optimality equation.
\pi_*(s) = \arg\max_{a} \sum_{s', r} p(s', r | s, a) [r + \gamma v_*(s')]
2.6 Linear Programming
The Bellman optimality equation can be solved using linear programming. This is a less frequently used method for solving MDPs. The idea is as follows:
- If v(s) \geq r(s, a) + \gamma \sum_{s'} p(s' | s, a) v(s') for all s \in \mathcal{S} and a \in \mathcal{A}, then v(s) is an upper bound on v_*(s).
- v_*(s) must be the smallest such v(s).
The linear programming formulation of the Bellman optimality equation is as follows:
\begin{align*} \textnormal{minimize } & \sum_{s \in \mathcal{S}} \alpha_s v(s) \\ \textnormal{s.t. } & v(s) \geq r(s, a) + \gamma \sum_{s'} p(s' | s, a) v(s'), \quad \forall s \in \mathcal{S}, \forall a \in \mathcal{A} \end{align*}
where the constants \alpha_s are arbitrary positive numbers.
Note that linear programming methods become impractical at a much smaller number of states than do dynamic programming (DP) methods (by a factor of about 100). DP methods are introduced in the next chapter.
2.7 Python Implementation
2.7.1 Linear Programming for the Cliff Walking Problem
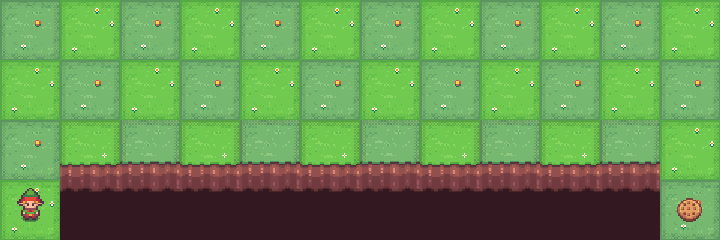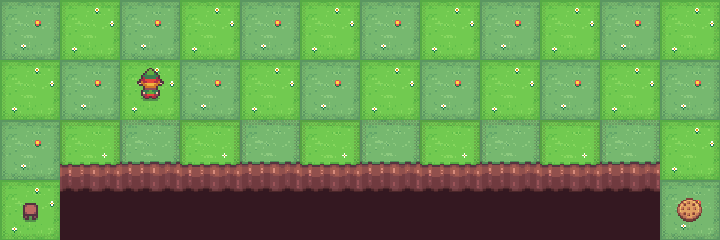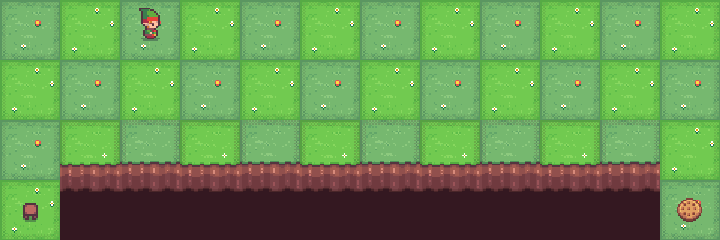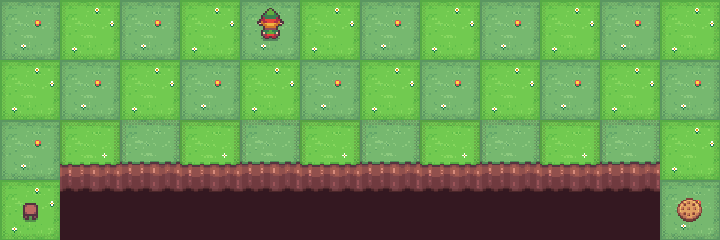
The goal is to find the optimal policy for moving an agent from a starting position to a goal position as quickly as possible while avoiding falling off a cliff.
See the animation of the Cliff Walking environment.
The following function solves the linear program with Gurobi. Save it as lp_solver.py so that the script below can import it.
# r: reward matrix, n_state * n_action
# p: transition probability matrix, n_state * n_action * n_state
# gamma: discount factor

from gurobipy import GRB, Model, quicksum

def lp_solver(r, p, gamma):

    action_set = set(range(r.shape[1]))
    state_set = set(range(r.shape[0]))
    n_state = len(state_set)

    # create a model instance
    model = Model()

    # create variables
    for s in range(n_state):
        model.addVar(name=f'v_{s}', lb=-GRB.INFINITY)

    # update the model
    model.update()

    # create constraints
    for state in state_set:
        for action in action_set:
            model.addConstr(model.getVarByName(f'v_{state}') >= quicksum(
                gamma * p[state, action, next_state] * model.getVarByName(f'v_{next_state}') for next_state in state_set ) + r[state, action])

    # set objective
    model.setObjective(quicksum(model.getVarByName(
        f'v_{state}') for state in state_set ), GRB.MINIMIZE)

    # optimize
    model.optimize()

    return model
The following script builds the reward matrix r and the transition probability matrix p from the Gymnasium environment, solves the MDP, and prints the optimal value function and policy.
import gymnasium as gym
import numpy as np
from lp_solver import lp_solver

# create an environment
env = gym.make('CliffWalking-v1')
n_state = env.unwrapped.nS
n_action = env.unwrapped.nA
state_set = set(range(n_state))
action_set = set(range(n_action))
# The player cannot be at the cliff, nor at the goal
terminal_state_set = [47]
unreachable_state_set = [37, 38, 39, 40, 41, 42, 43, 44, 45, 46]
# the reachable state set is the set of all states except the cliff and the goal.
# only the states in the reachable state set are considered in the optimization problem
reachable_state_set = set(set(state_set) - set(terminal_state_set) - set(unreachable_state_set))

# set parameters
gamma = 1

# initialize reward and transition probability
r = np.zeros((n_state, n_action))
p = np.zeros((n_state, n_action, n_state))

for state in reachable_state_set:
    for action in action_set:
        for prob, next_state, reward, terminated in env.unwrapped.P[state][action]:
            r[state, action] += prob * reward
            p[state, action, next_state] += prob

# solve the mdp problem using linear programming
model = lp_solver(r, p, gamma)

# state value
value_function = {}
for state in reachable_state_set:
    value_function[state] = model.getVarByName(f'v_{state}').x

policy = {}
for state in terminal_state_set:
    value_function[state] = 0

for state in reachable_state_set:
    q_max_value = -np.inf
    for action in action_set:
        q_value_temp = sum([prob * (reward + gamma * value_function[next_state])
                            for prob, next_state, reward, terminated in env.unwrapped.P[state][action]])
        if q_value_temp > q_max_value:
            q_max_value = q_value_temp
            policy[state] = action

# print value function 4*12, 1 digit after the decimal point

print('value function = ')
for i in range(4):
    for j in range(12):
        if i * 12 + j in value_function:
            print('{:.1f}'.format(value_function[i * 12 + j]), end='\t')
        else:
            print('x', end='\t')
    print()

print('optimal policy = ')
for i in range(4):
    for j in range(12):
        if i * 12 + j in policy:
            print(policy[i * 12 + j], end='\t')
        else:
            print('x', end='\t')
    print()

model.write("model.lp")
2.8 Summary
- Markov decision processes (MDPs) are used to formulate sequential decision-making problems.
- An MDP is a tuple (\mathcal{S}, \mathcal{A}, p, r, \gamma).
- The Bellman optimality equation is a system of nonlinear equations that can be solved to find the optimal value function.
- Linear programming can be used to find the optimal value function.
2.9 Exercises
Exercise 2.1 (Formulating your own MDP) Choose a sequential decision-making problem that interests you. It can come from a game, a hobby, your daily life, or your field of study. Formulate it as an MDP (\mathcal{S}, \mathcal{A}, p, r, \gamma) by answering the following questions.
Who is the agent, and what is the environment? What does one time step correspond to in your problem?
Define the state set \mathcal{S} and the action sets \mathcal{A}(s). Does your state have the Markov property? If not, what information would you add to the state?
Define the reward R_{t+1}. Would an agent that maximizes the expected return achieve your goal, or could it obtain a high return in a way you did not intend?
Describe the dynamics function p(s', r | s, a). Where does the uncertainty in the next state and the reward come from? Give p(s', r | s, a) explicitly for one state-action pair (s, a), and compute r(s, a) for that pair.
Is your task episodic or continuing? If it is episodic, what are the terminal states? Choose a discount factor \gamma and justify your choice.
What does your MDP simplify or leave out compared with the real problem?